
Launch day is a run of show
A product launch is not a project plan. The project plan is the eight weeks before it.
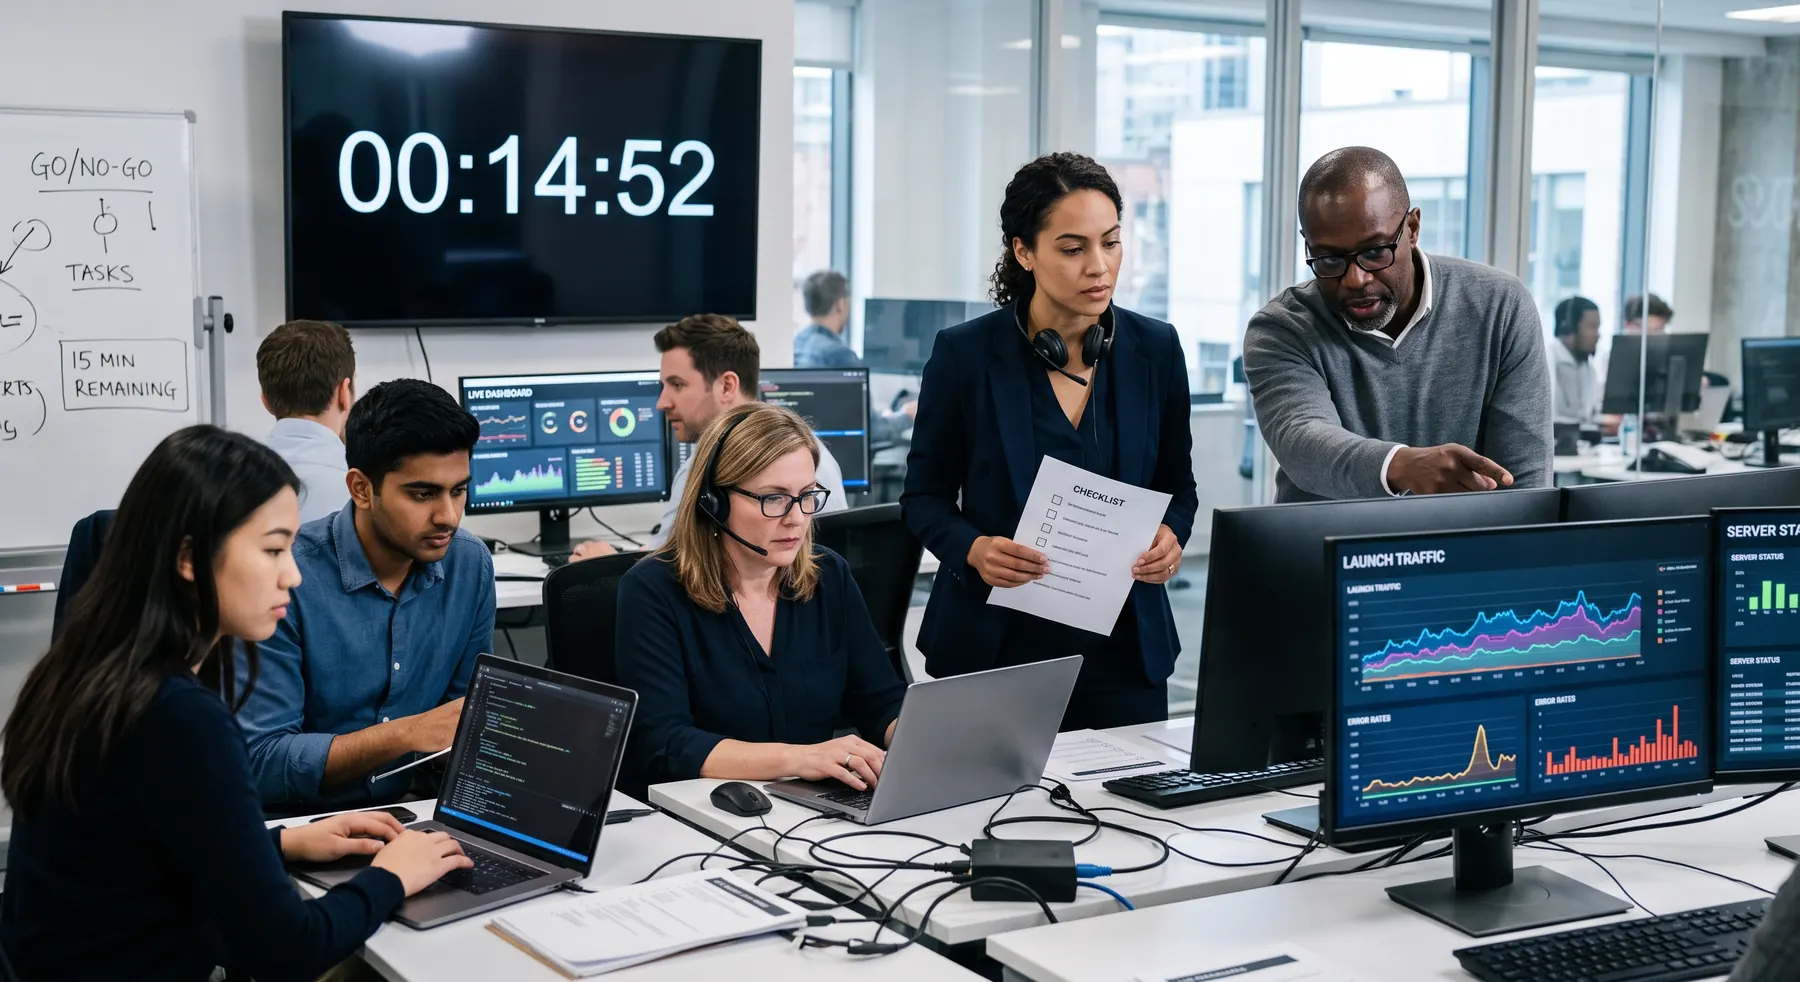
Launch day itself is a cue-based run of show: a sequence of tightly coupled actions, many of them irreversible, performed by people in different functions and often different time zones, where the order matters more than the clock. It has far more in common with running a live event than with the sprint that built the thing — which is why it should be documented the way a run of show is documented, not as a task list.
The practical consequence: write it in T-minus offsets. T-0 is the moment the release goes live. Everything else is T-90min, T-30min, T+15min.
This matters because T-0 moves. A build fails, a legal review comes back late, a partner is not ready. When launch slips two hours, a wall-clock timeline needs forty lines rewritten and re-communicated to nine people. A T-minus timeline needs one number changed, and everything recalculates from it.
The canonical sequence
| Offset | Action | Owner |
|---|---|---|
| T-24h | Go/no-go gate — every function confirms | Launch lead |
| T-4h | Final asset check: pages staged, pricing live in test, docs merged | Marketing + Product |
| T-2h | Internal enablement — support, sales, success briefed | Enablement |
| T-90min | Support macros and help centre articles staged | Support |
| T-60min | War room opens; monitoring dashboards up | Engineering |
| T-30min | Final go/no-go confirmation from engineering | Eng lead |
| T-0 | Release live / deploy complete | Engineering |
| T+5min | Smoke tests pass; verify purchase and signup paths | QA |
| T+15min | Embargo lifts; press live | Comms |
| T+20min | Owned channels: site, blog, changelog, email | Marketing |
| T+30min | Social, community, forums | Social |
| T+60min | First monitoring checkpoint | Launch lead |
| T+4h | Second checkpoint; early metrics; triage | Launch lead |
| T+24h | Retro scheduled; day-one numbers circulated | Launch lead |
Two orderings in that table are non-obvious and both are load-bearing.
Internal goes before external. Always.
T-2h internal enablement is not a courtesy — it is the difference between a launch and an incident.
The moment the announcement is public, customers start asking questions. If a support agent learns about the new pricing tier from a customer, you have created an avoidable failure at the worst possible moment, in front of the people most likely to write about it.
Support, sales, and customer success each need different things, and they need them in hand before the first external signal:
- Support: known issues, workarounds, escalation path, staged macros, and an honest statement of what is not in this release.
- Sales: positioning, pricing, what it replaces, and what to say to customers who bought the old thing last week.
- Success: migration implications and which accounts are affected.
The last item in each list is the one that gets skipped and the one that generates the angry email.
The go/no-go gate
Twenty-four hours out, every function says yes or no. Binary. Named person per function.
The gate's real value is not the information — the launch lead usually knows the state of things already. It is that the gate makes stopping legitimate.
Without an explicit decision point, launches proceed by momentum. Everyone has a reservation, nobody wants to be the person who halted a launch the whole company has been waiting for, and so a known problem ships. A scheduled gate where "no" is one of two expected answers removes the social cost of saying it.
Give each function a defined question. Not "are you ready?" but "is there anything that should stop this?" The second question gets honest answers; the first gets optimistic ones.
Build your launch timeline freeTime zones and embargoes
Pick one reference zone. State it on every line. Then express everything as T-minus offsets anyway.
Embargoes need extra care because they are the one place ambiguity has consequences you cannot undo. Write embargo lifts in UTC alongside local time — that is the convention press work in, and an embargo broken because a journalist in another country read "9am" as their own 9am is a real and recurring failure.
If you are launching across regions, decide explicitly whether the embargo lifts simultaneously worldwide or rolls with local morning. Both are defensible. Not deciding is not.
When to launch
Mid-morning in your primary market, Tuesday through Thursday.
Mid-morning gives a full working day of coverage and a full team available if something breaks. Tuesday-to-Thursday avoids the Monday backlog and the Friday exodus.
A Friday afternoon launch has the same flaw as a 17:00 launch: the problem surfaces when nobody is there to fix it, and it then compounds unattended for the entire weekend. The only good reason to launch on a Friday is that you are deliberately seeking a quiet news cycle, which is a strategy for burying something rather than announcing it.
The rollback path
Write it down, before launch day, with three things stated explicitly:
- What triggers a rollback — a specific error rate, a specific broken path, not "if things look bad".
- Who can call it — one named person, with one named deputy.
- What rolling back involves — including the comms. A rolled-back launch still needs something said to the people who saw the announcement.
Teams reliably document the technical rollback and reliably forget the communications half. The public blog post does not un-publish itself, and the press who covered it will ask.
Event planners running launch events alongside the release itself carry an extra layer: a venue, a livestream, and an audience, all keyed to a T-0 that engineering controls. That is a genuine dependency, and the launch timeline should show it as one — the room does not care that the deploy is running long, but it will notice.
Structures worth adapting sit in the corporate template collection, and for the live-event portion of a launch the run of show builder is the right tool.